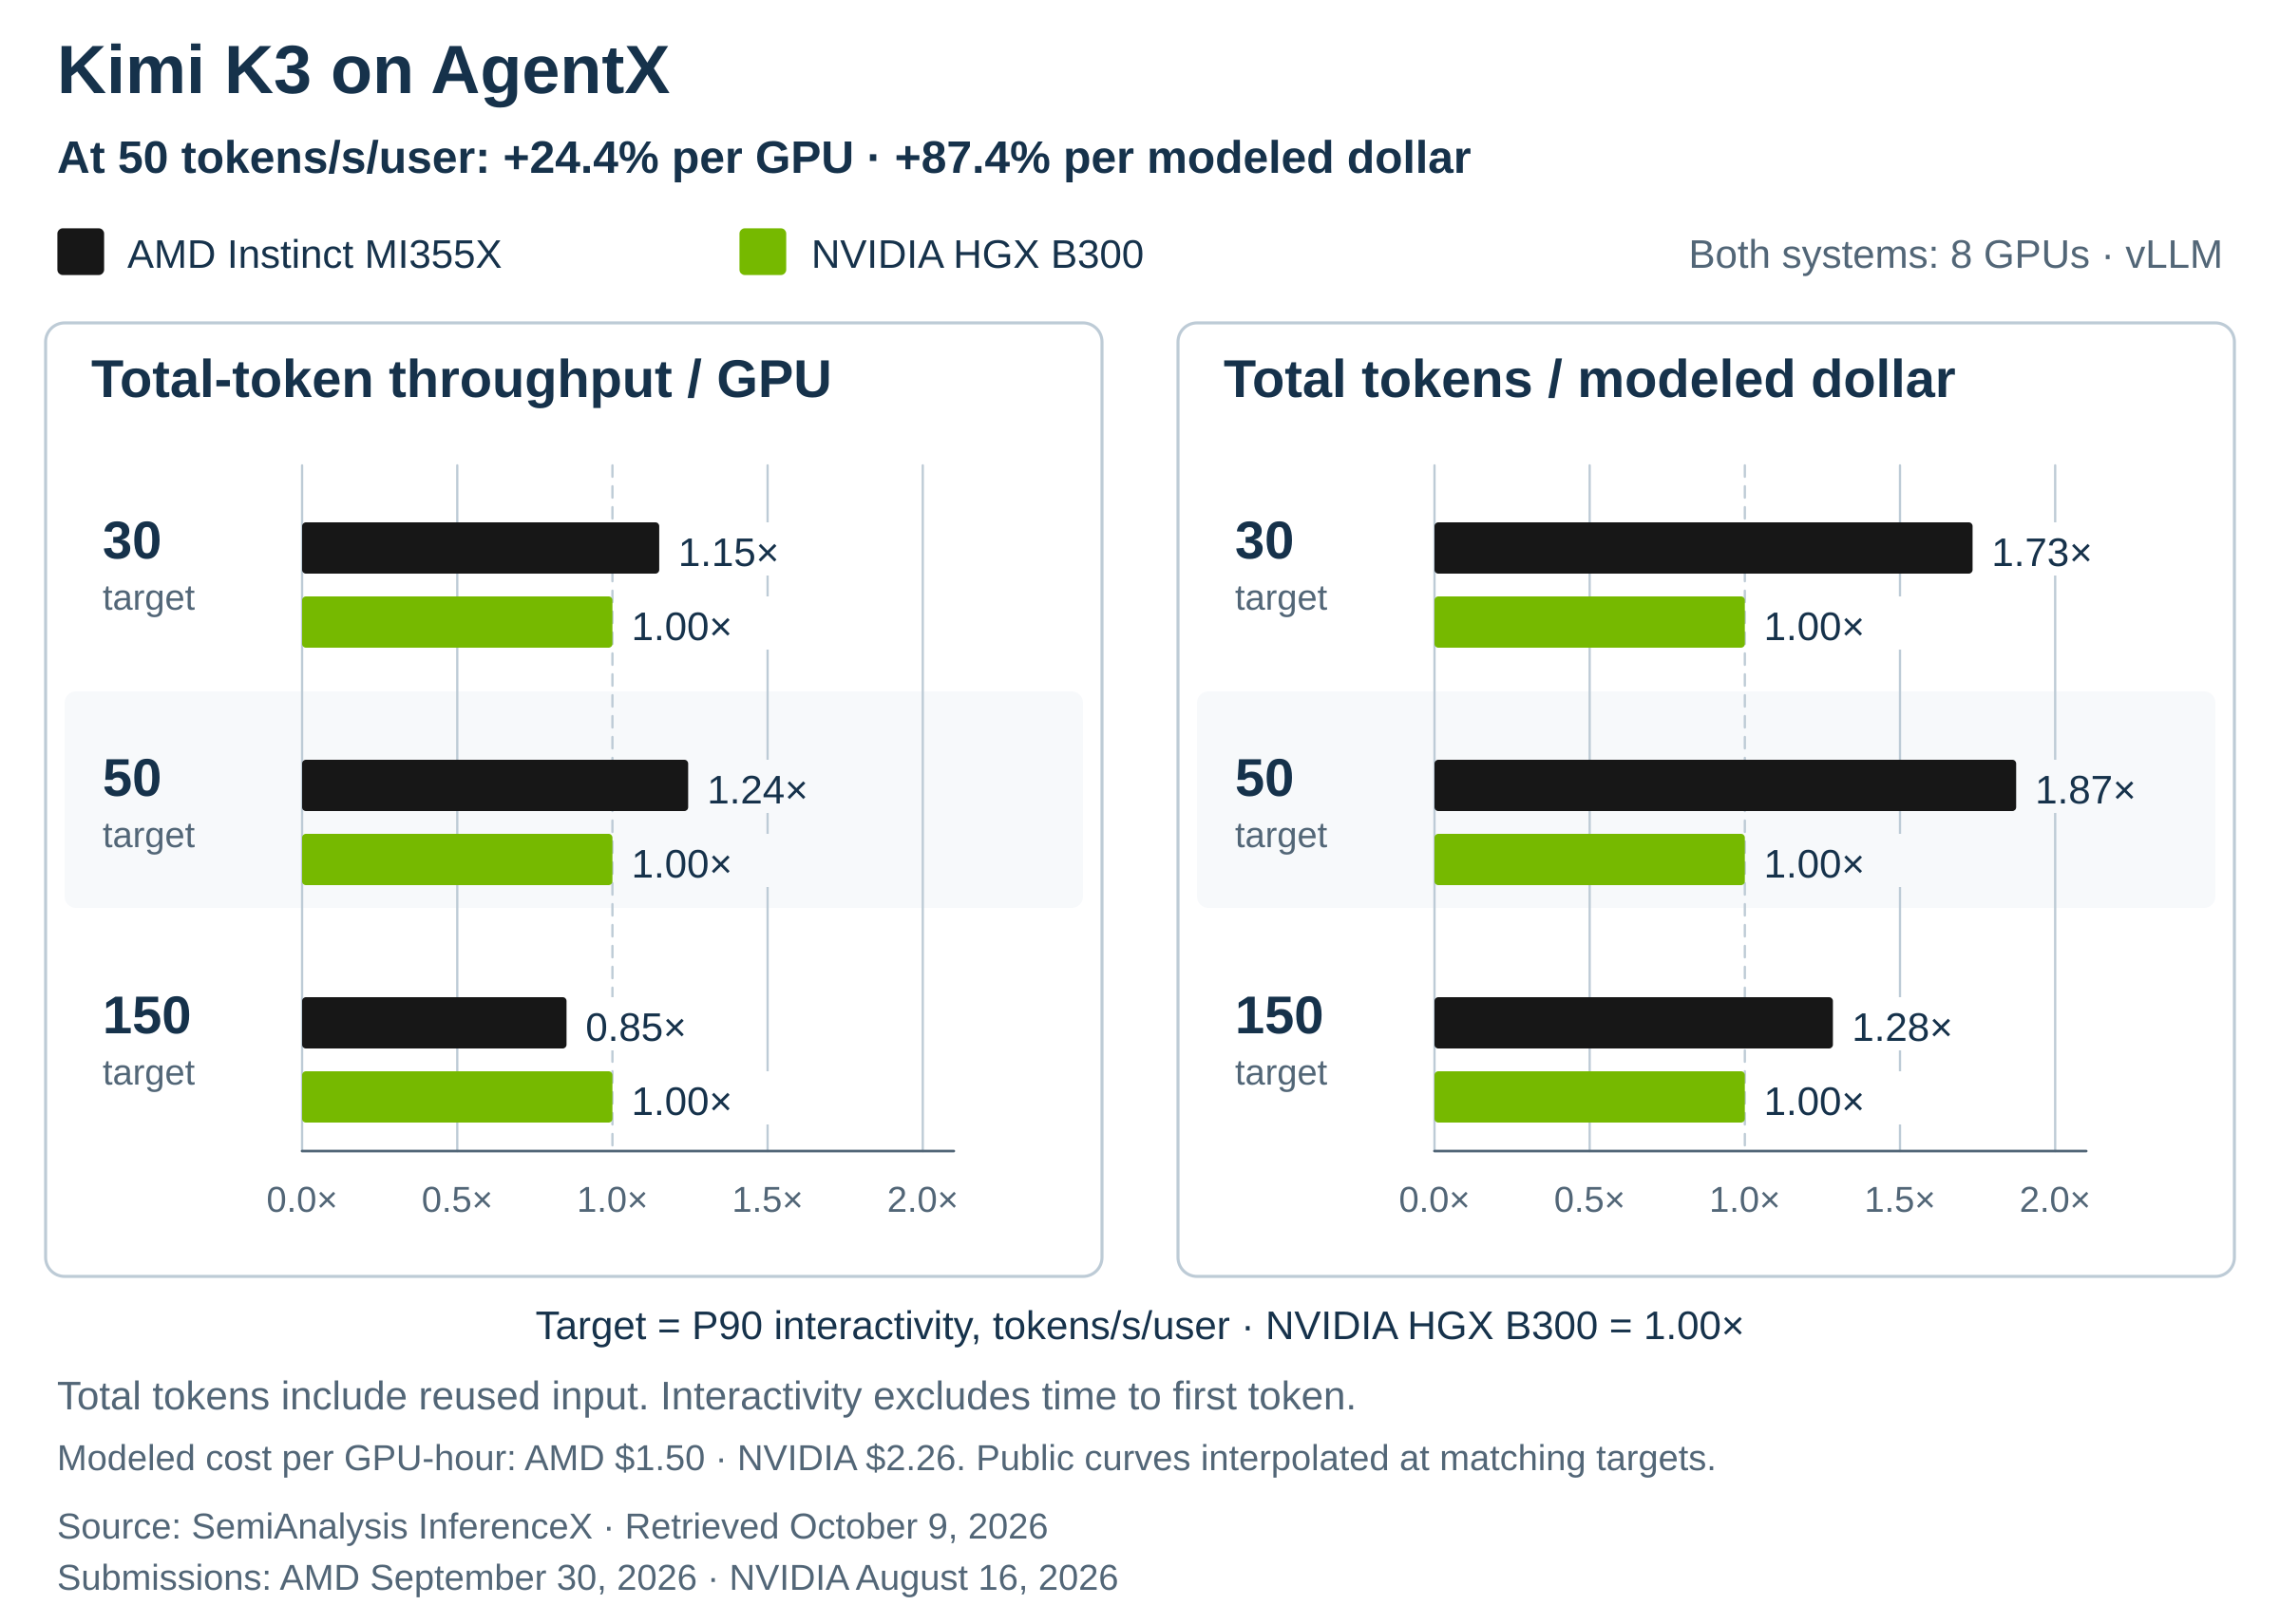
Scaling Kimi K3 on AMD Instinct MI355X: Matching NVIDIA HGX B300 Throughput per GPU on AgentX
·24 min read
Inside the Kimi K3 optimization effort: understanding the bottlenecks and the decisions that made inference faster
2 posts
Inside the Kimi K3 optimization effort: understanding the bottlenecks and the decisions that made inference faster
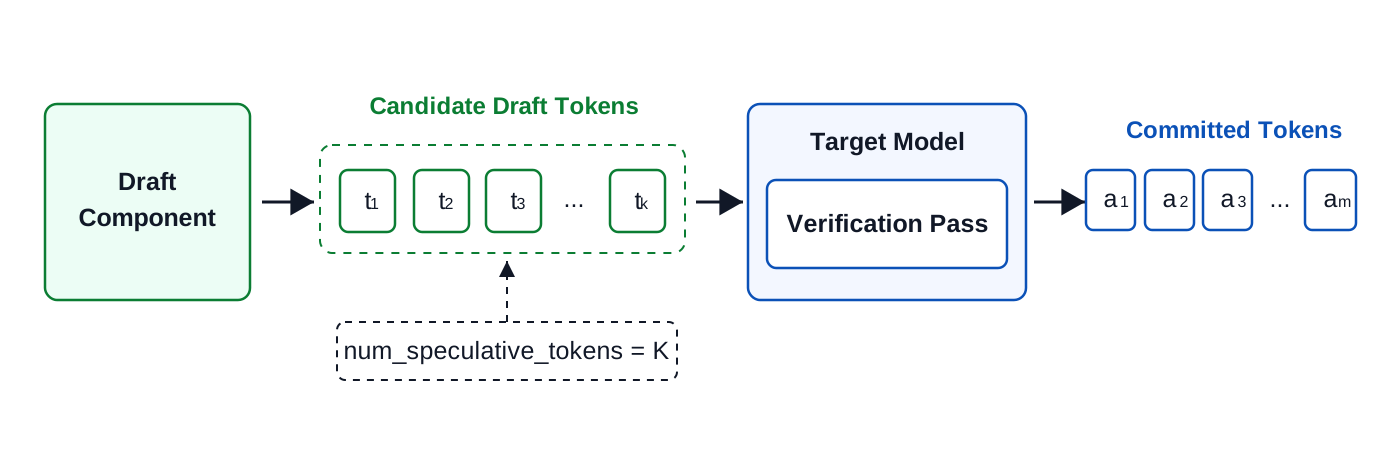
A practical guide to speculative decoding in vLLM on AMD GPUs, covering draft-and-verify mechanics, MTP, EAGLE-3, DFlash, DSpark, configuration, tuning, and benchmark results.