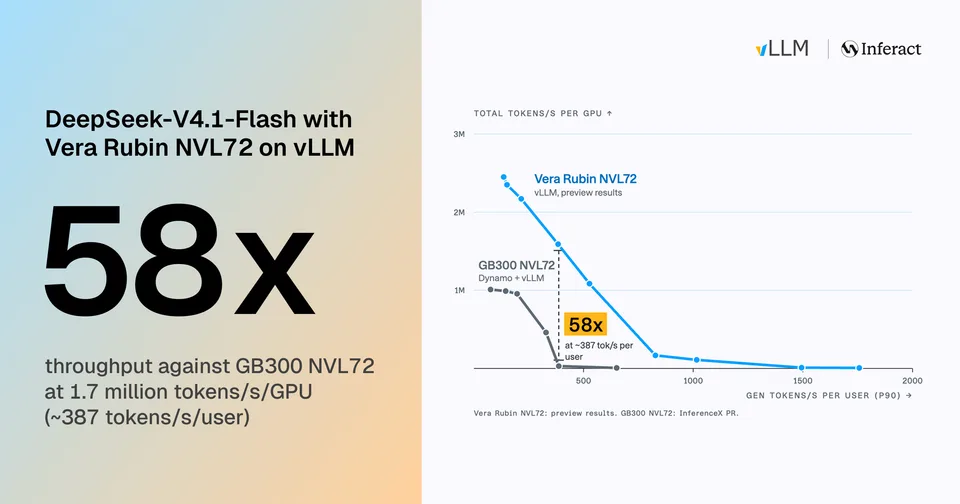
DeepSeek-V4.1-Flash on Vera Rubin NVL72: 58x Throughput vs. GB300 NVL72 at 387 tokens/s
·19 min read
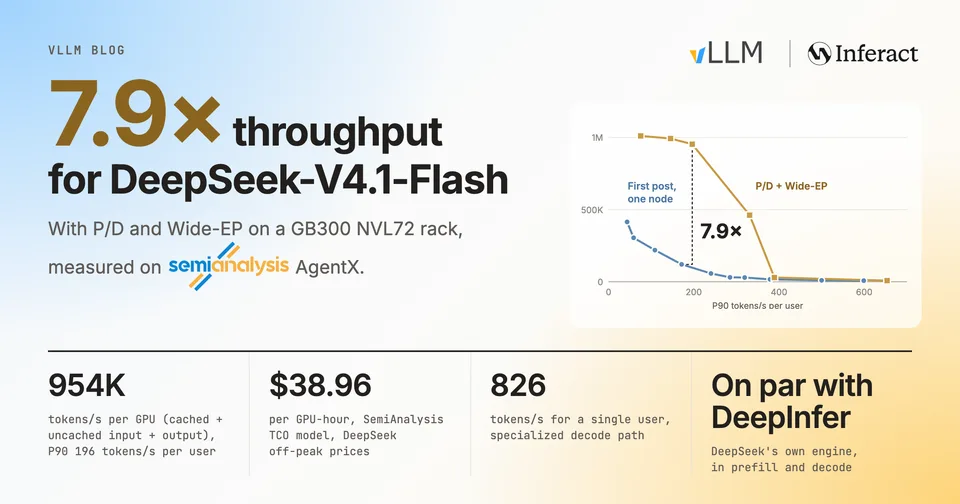
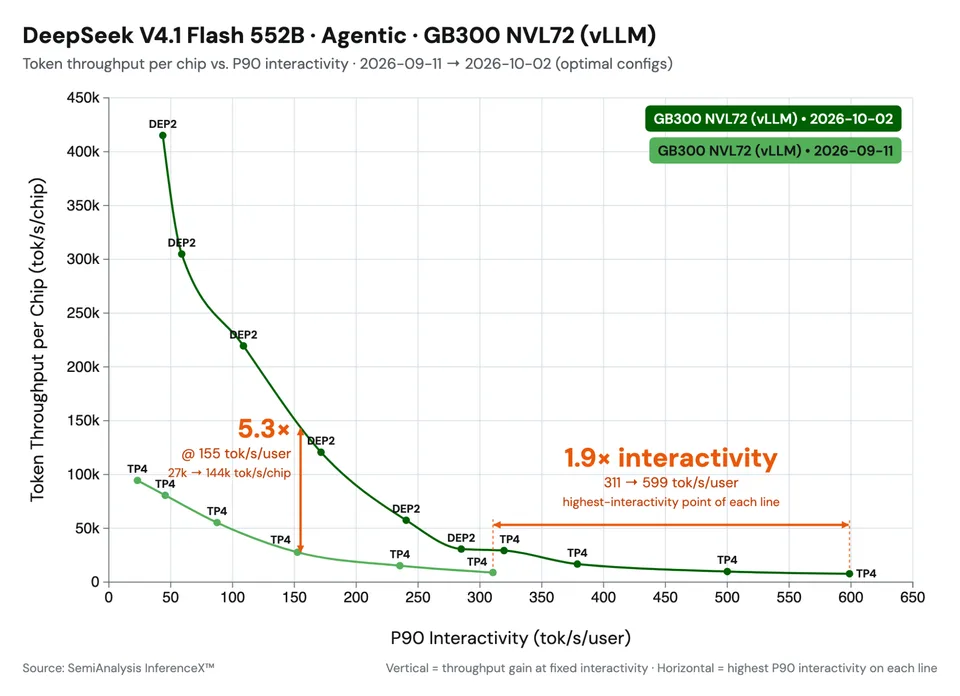
On one NVIDIA Vera Rubin NVL72 rack, vLLM serves DeepSeek-V4.1-Flash on SemiAnalysis AgentX at 1.7M tokens/s per GPU at a P90 of 387 tokens/s per user, 58x GB300 NVL72 at the same interactivity.