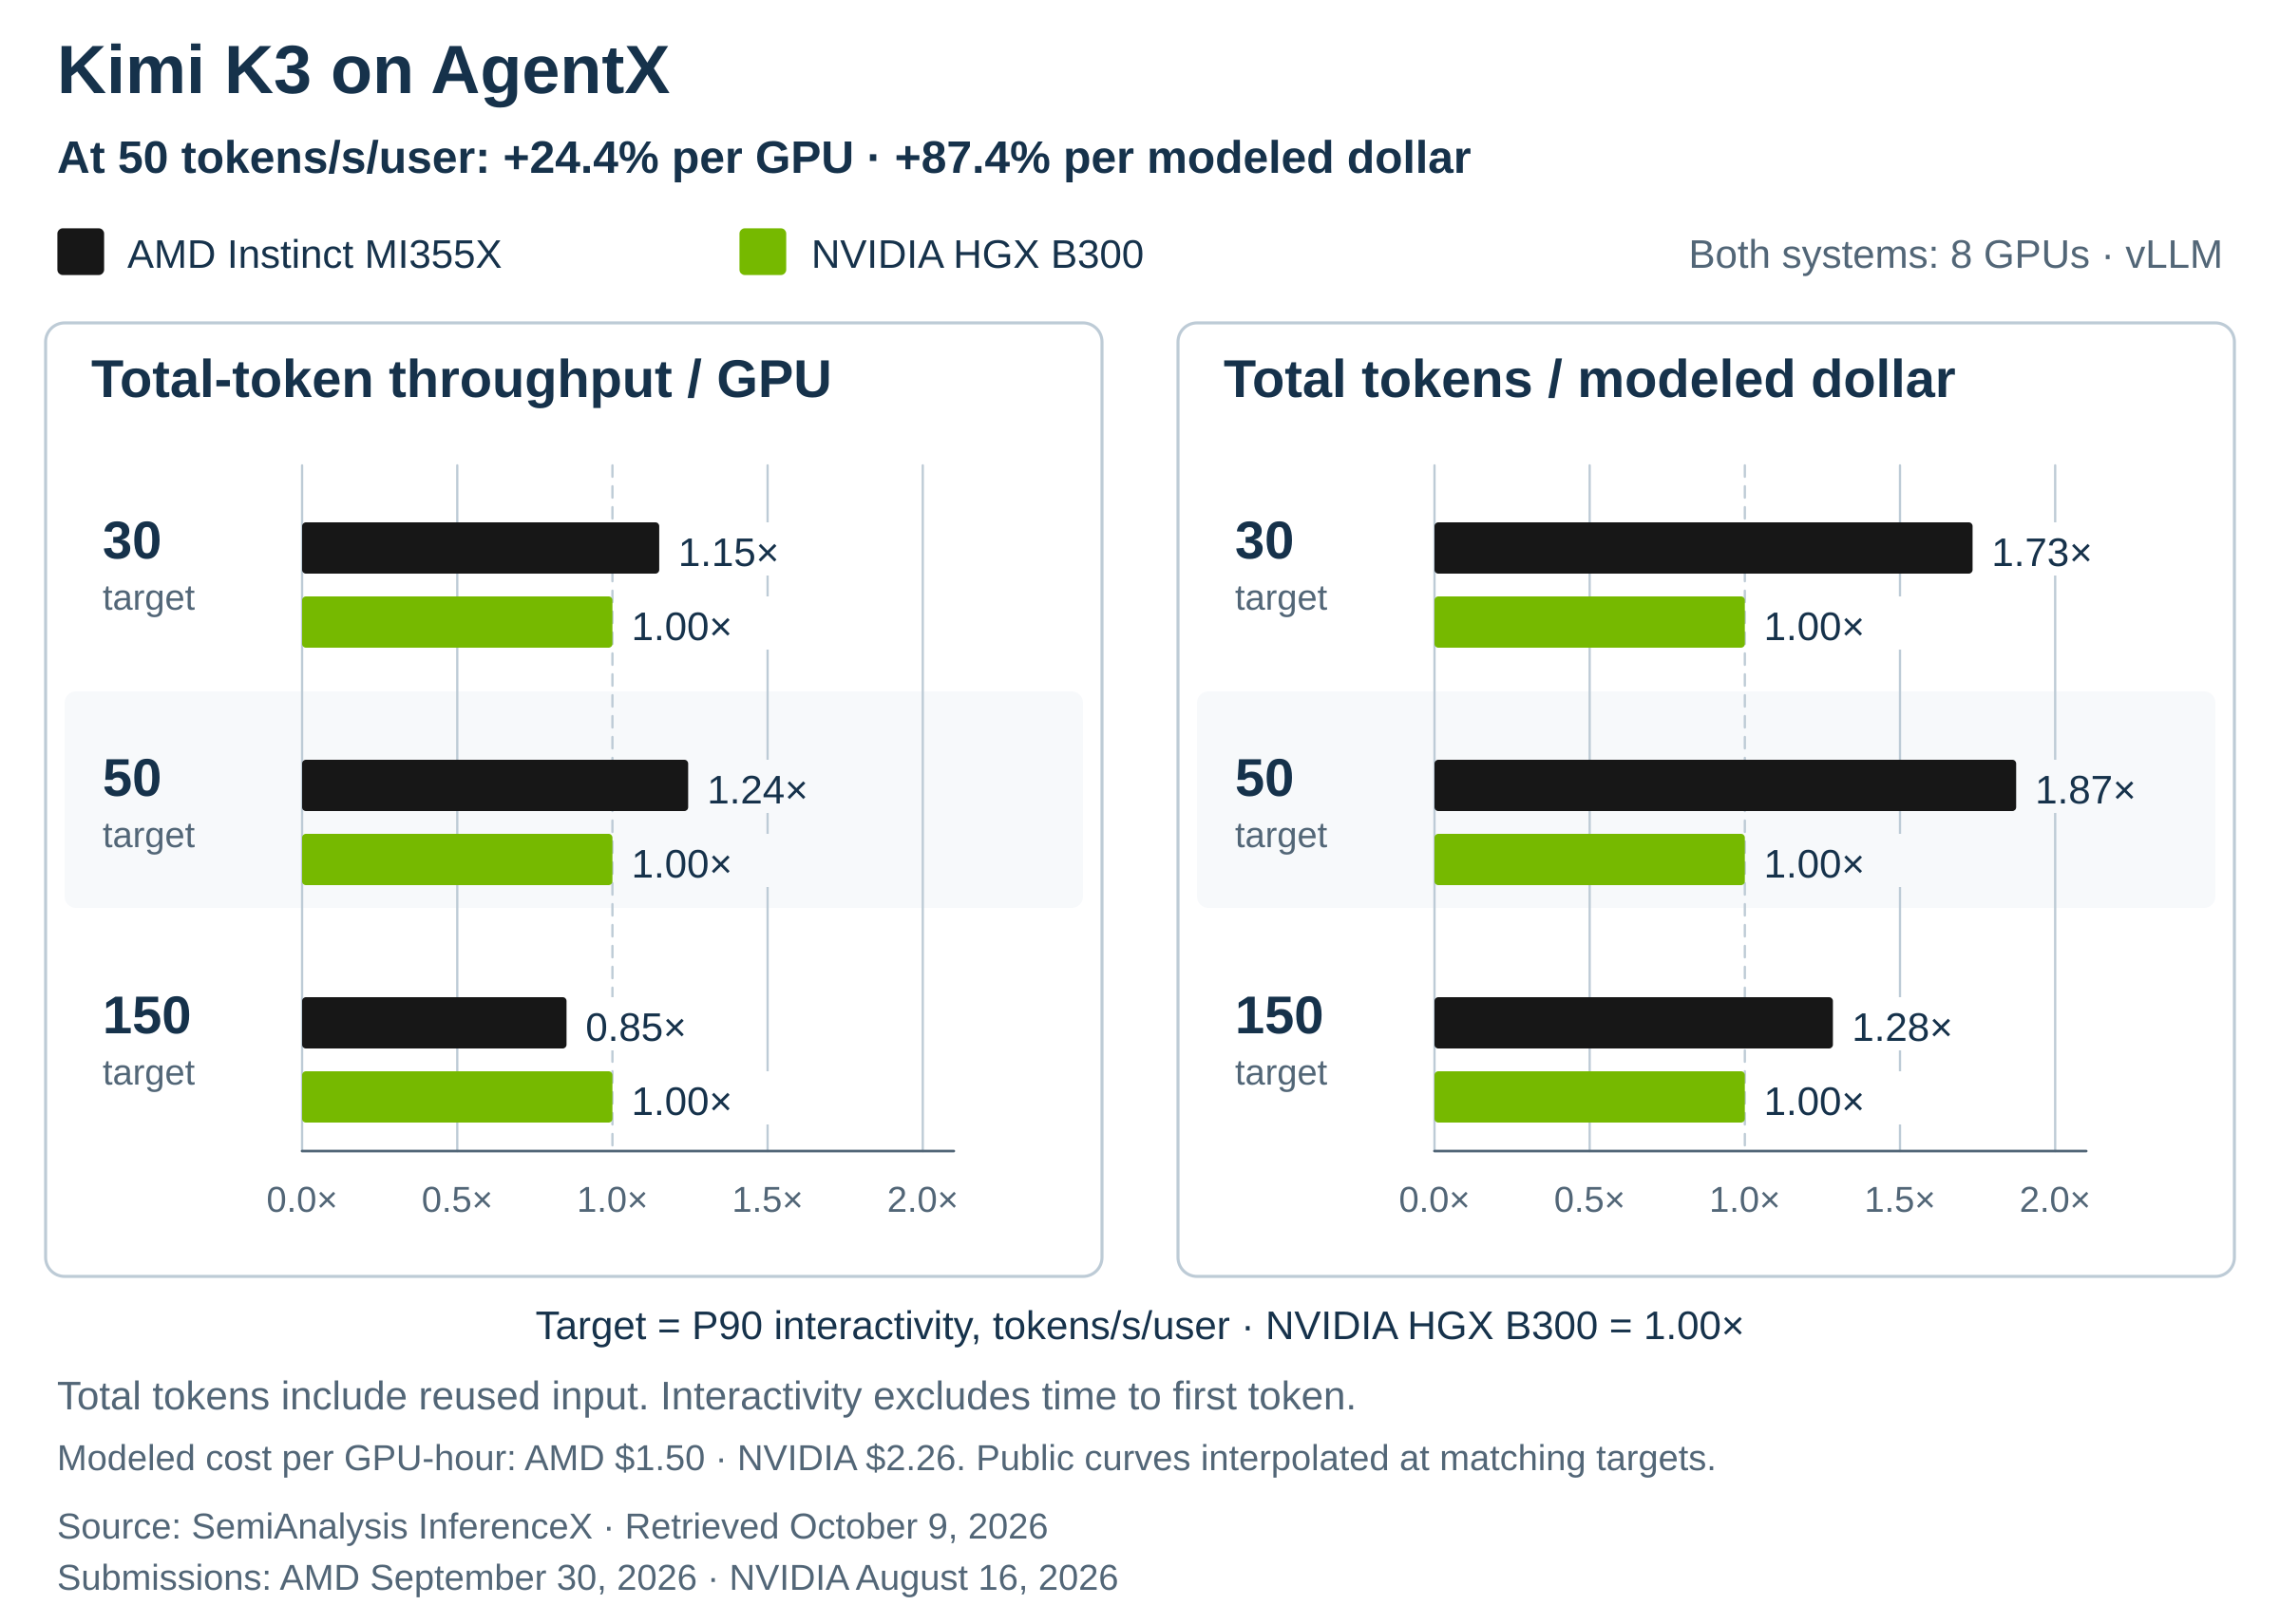
Scaling Kimi K3 on AMD Instinct MI355X: Matching NVIDIA HGX B300 Throughput per GPU on AgentX
·24 min read
Inside the Kimi K3 optimization effort: understanding the bottlenecks and the decisions that made inference faster
4 posts
Inside the Kimi K3 optimization effort: understanding the bottlenecks and the decisions that made inference faster
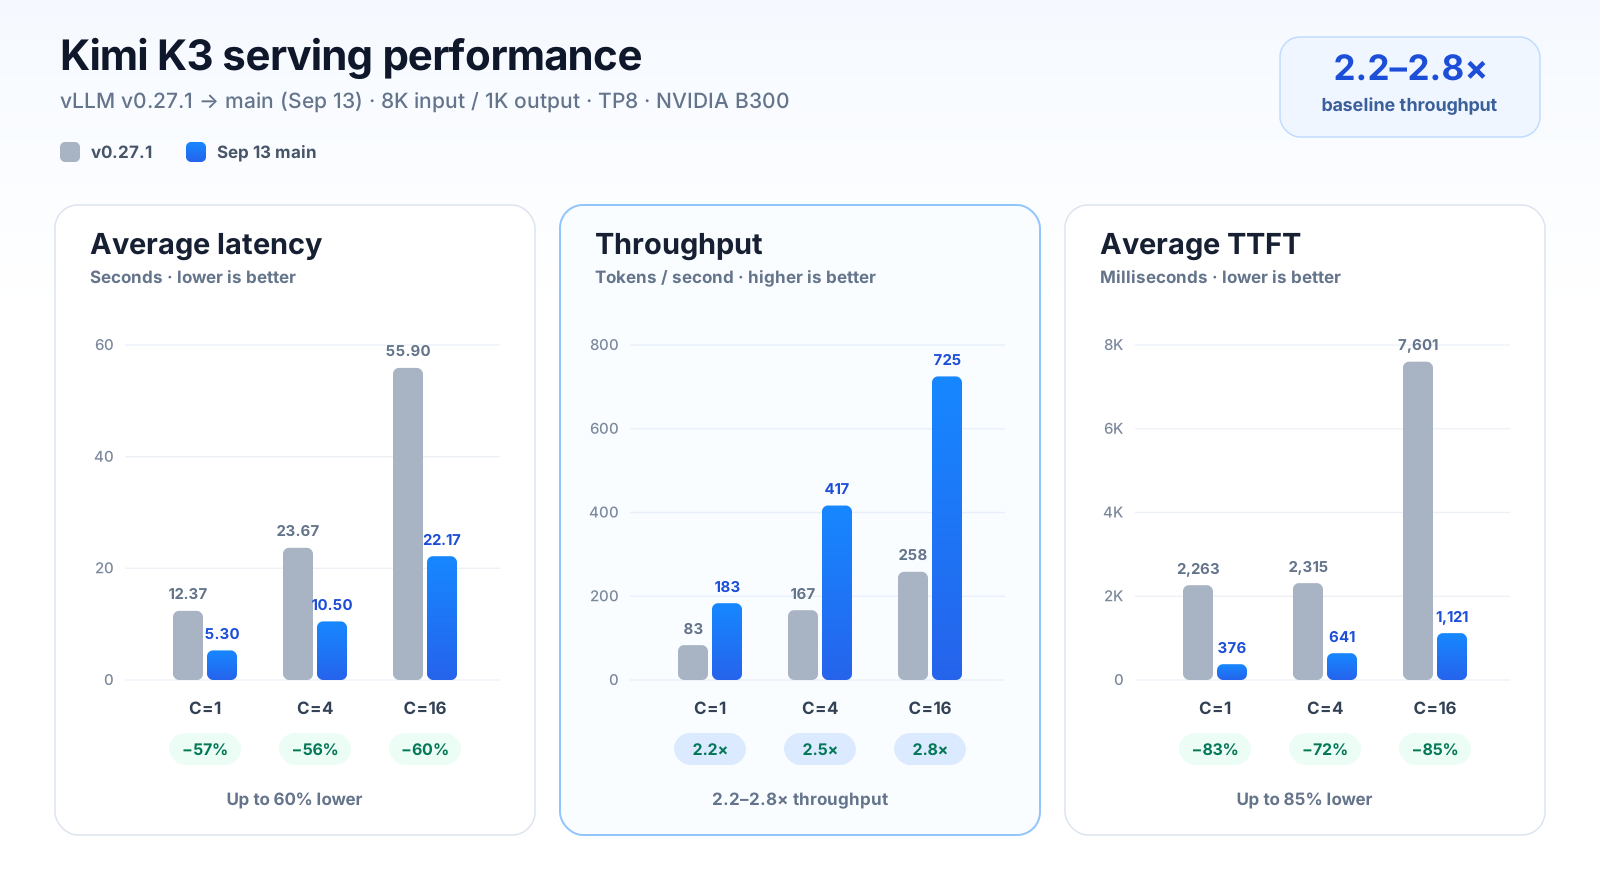
Kimi K3 serving optimizations across scheduling, KDA prefix caching, ReplaySSM state recovery, PD disaggregation and state offload, parallelism, MoE, and GPU kernels.
vLLM delivers day-0 Kimi K3 serving with hybrid KDA prefix caching, DSpark speculative decoding, production-scale disaggregation, and optimized kernels across NVIDIA and AMD GPUs.
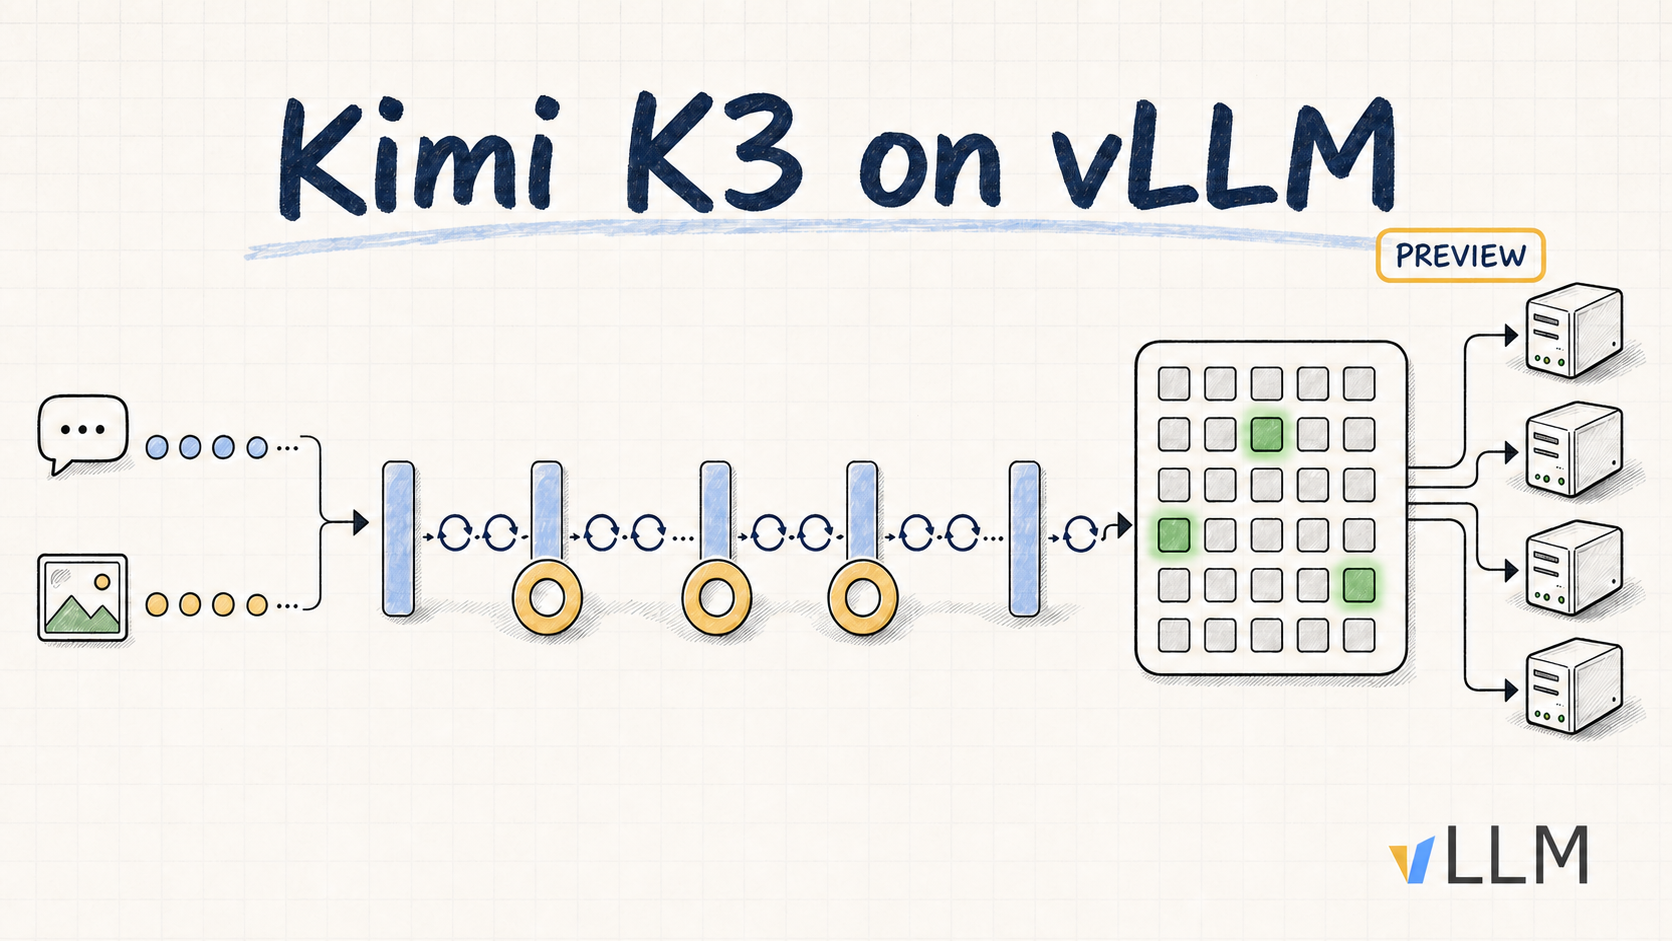
A preview of production-scale Kimi K3 support in vLLM, including KDA-aware prefix caching, fused kernels, optimized MXFP4 MoE, multimodal integration, and initial NVIDIA and AMD paths.