
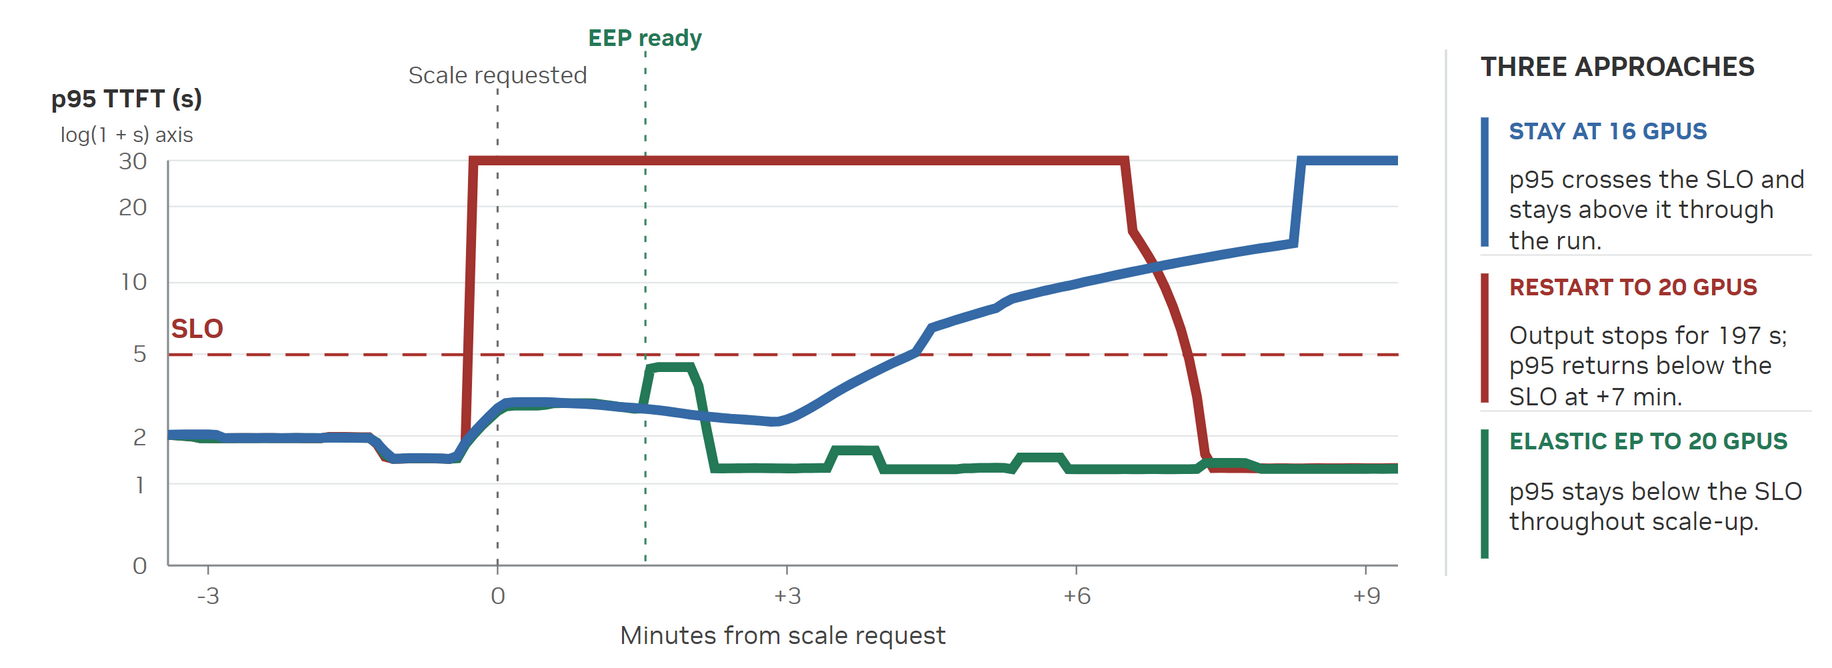
Achieving near-zero-downtime scaling in Elastic Expert Parallelism
·12 min read
How asynchronous preparation and NIXL EP enabled near-zero-downtime Elastic EP scaling in vLLM.

3 posts
How asynchronous preparation and NIXL EP enabled near-zero-downtime Elastic EP scaling in vLLM.
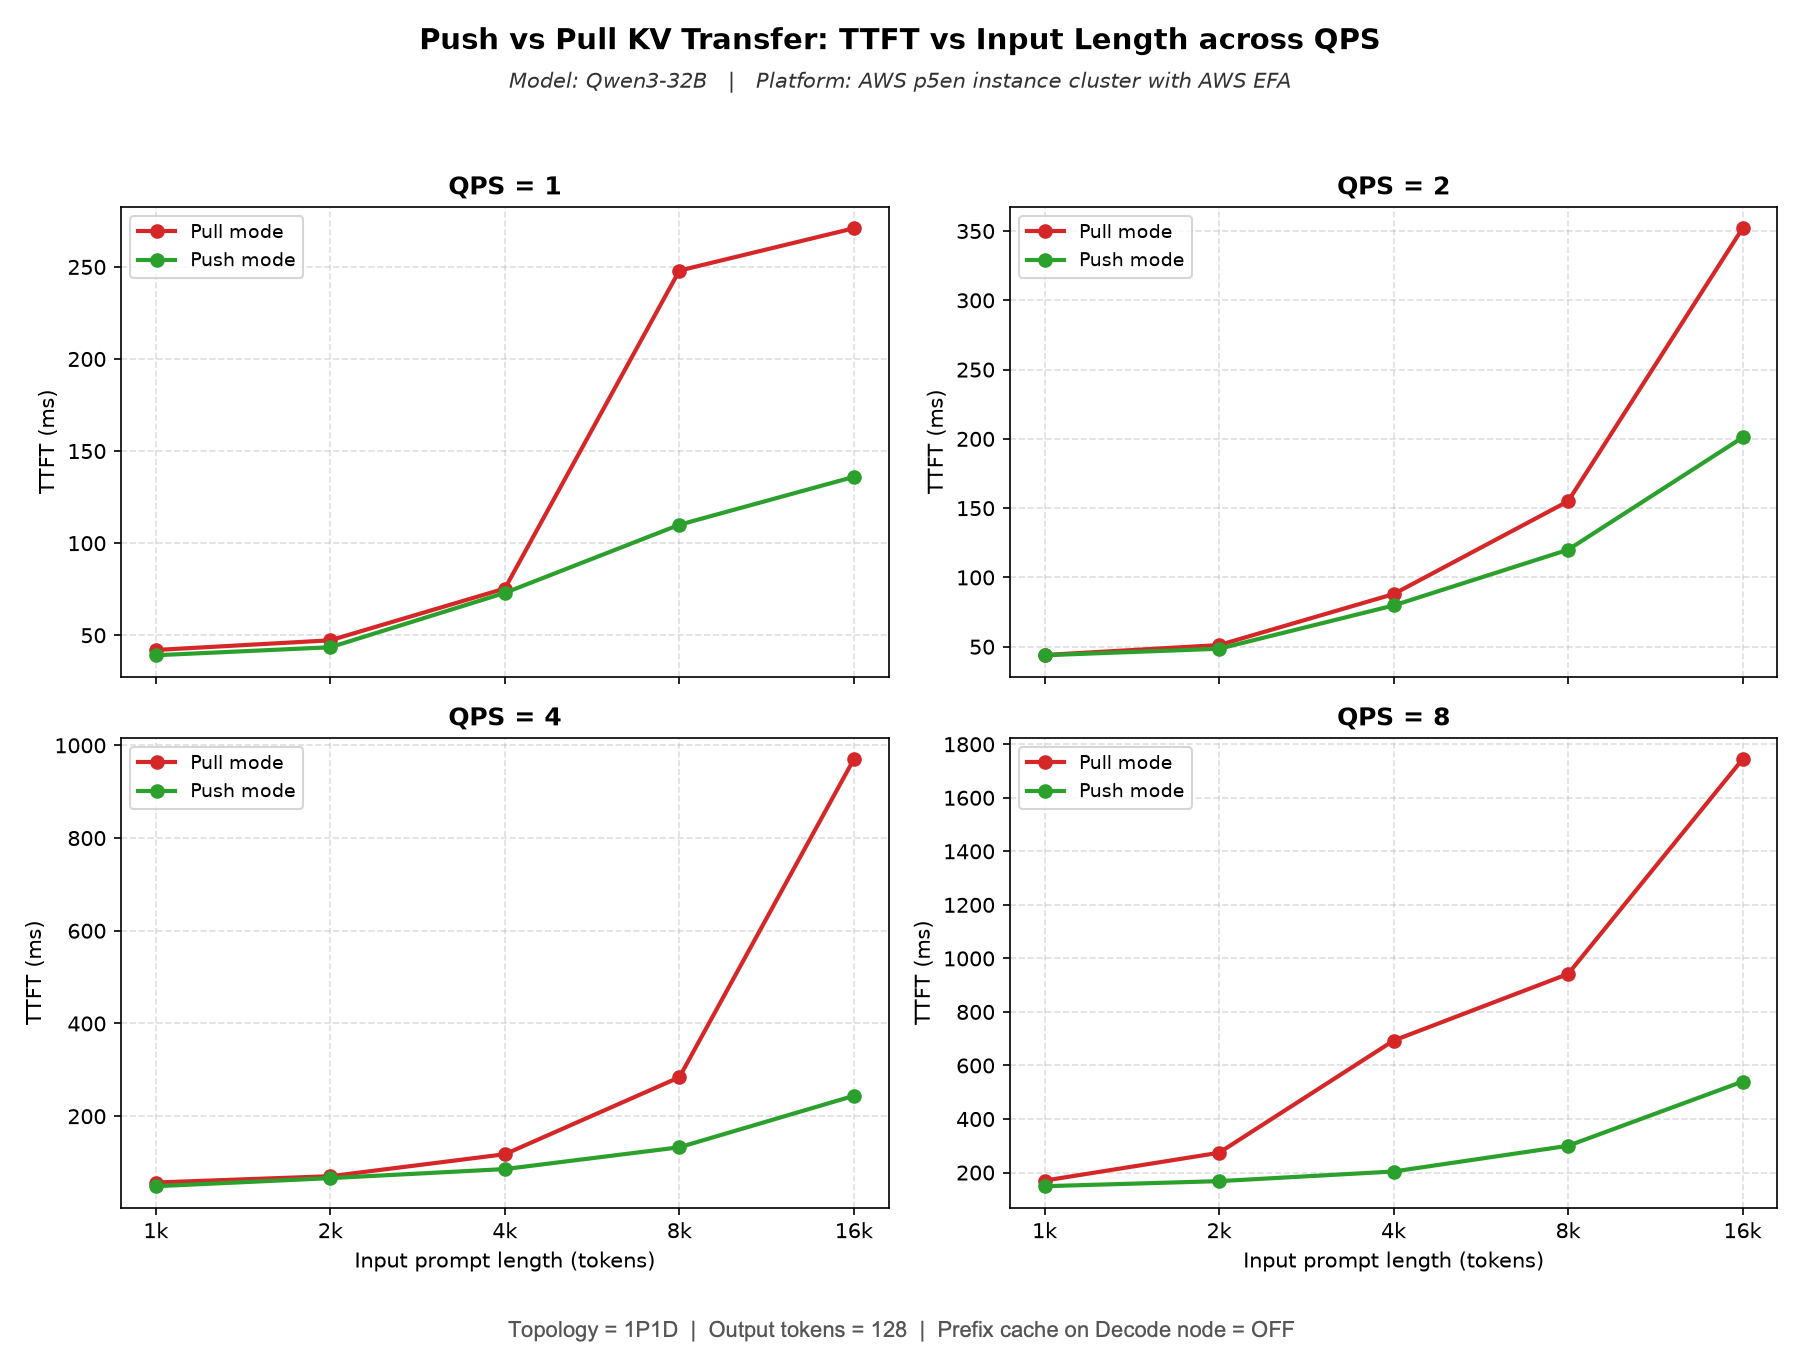
A push-based NIXL connector for vLLM disaggregated serving: the prefill instance writes KV directly into decode memory over RDMA, taking the router relay, decode-side allocation, and transfer setup off the TTFT critical path.
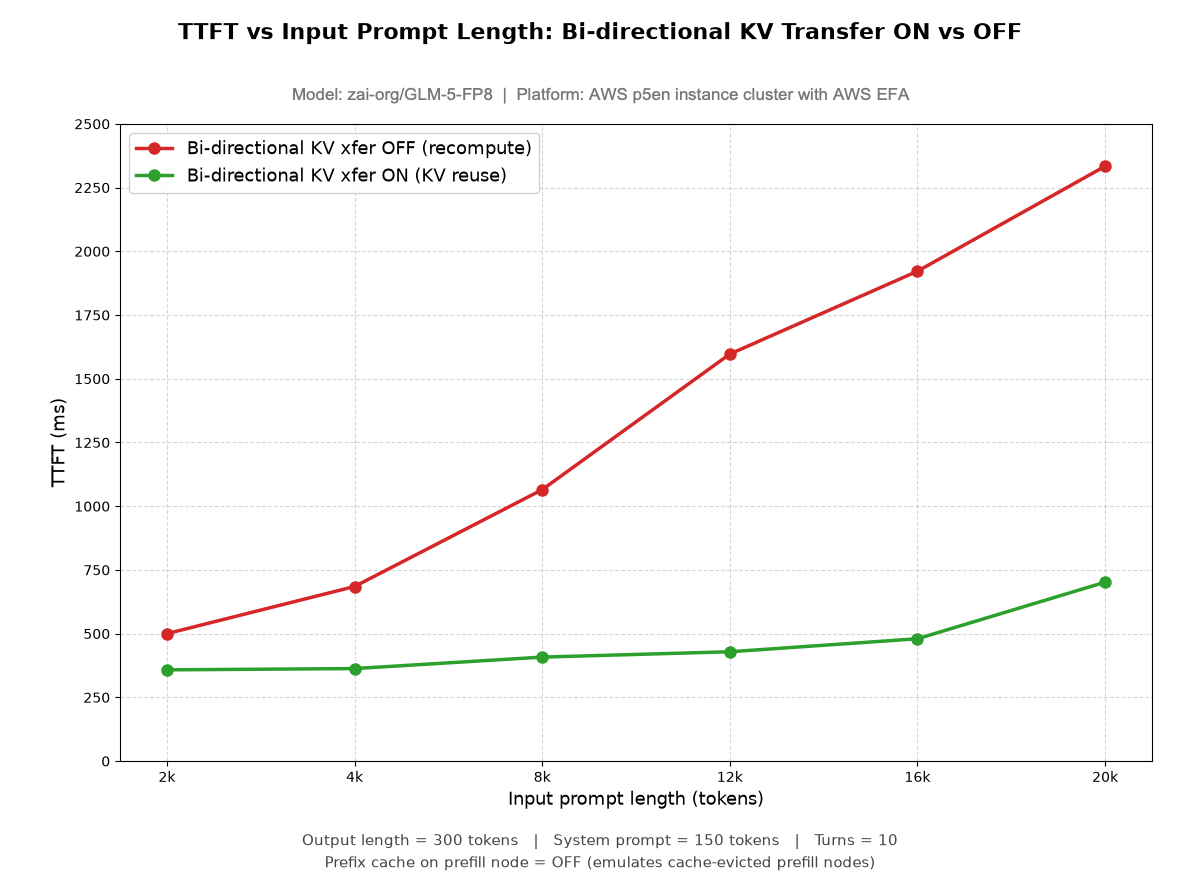
Bi-directional KV transfer lets vLLM prefill nodes reuse previously computed KV from decode nodes on later conversation turns, cutting redundant prefill recompute and reducing TTFT by up to 3.3x on long multi-turn prompts.