Reducing vLLM startup time with one uv flag
·7 min read
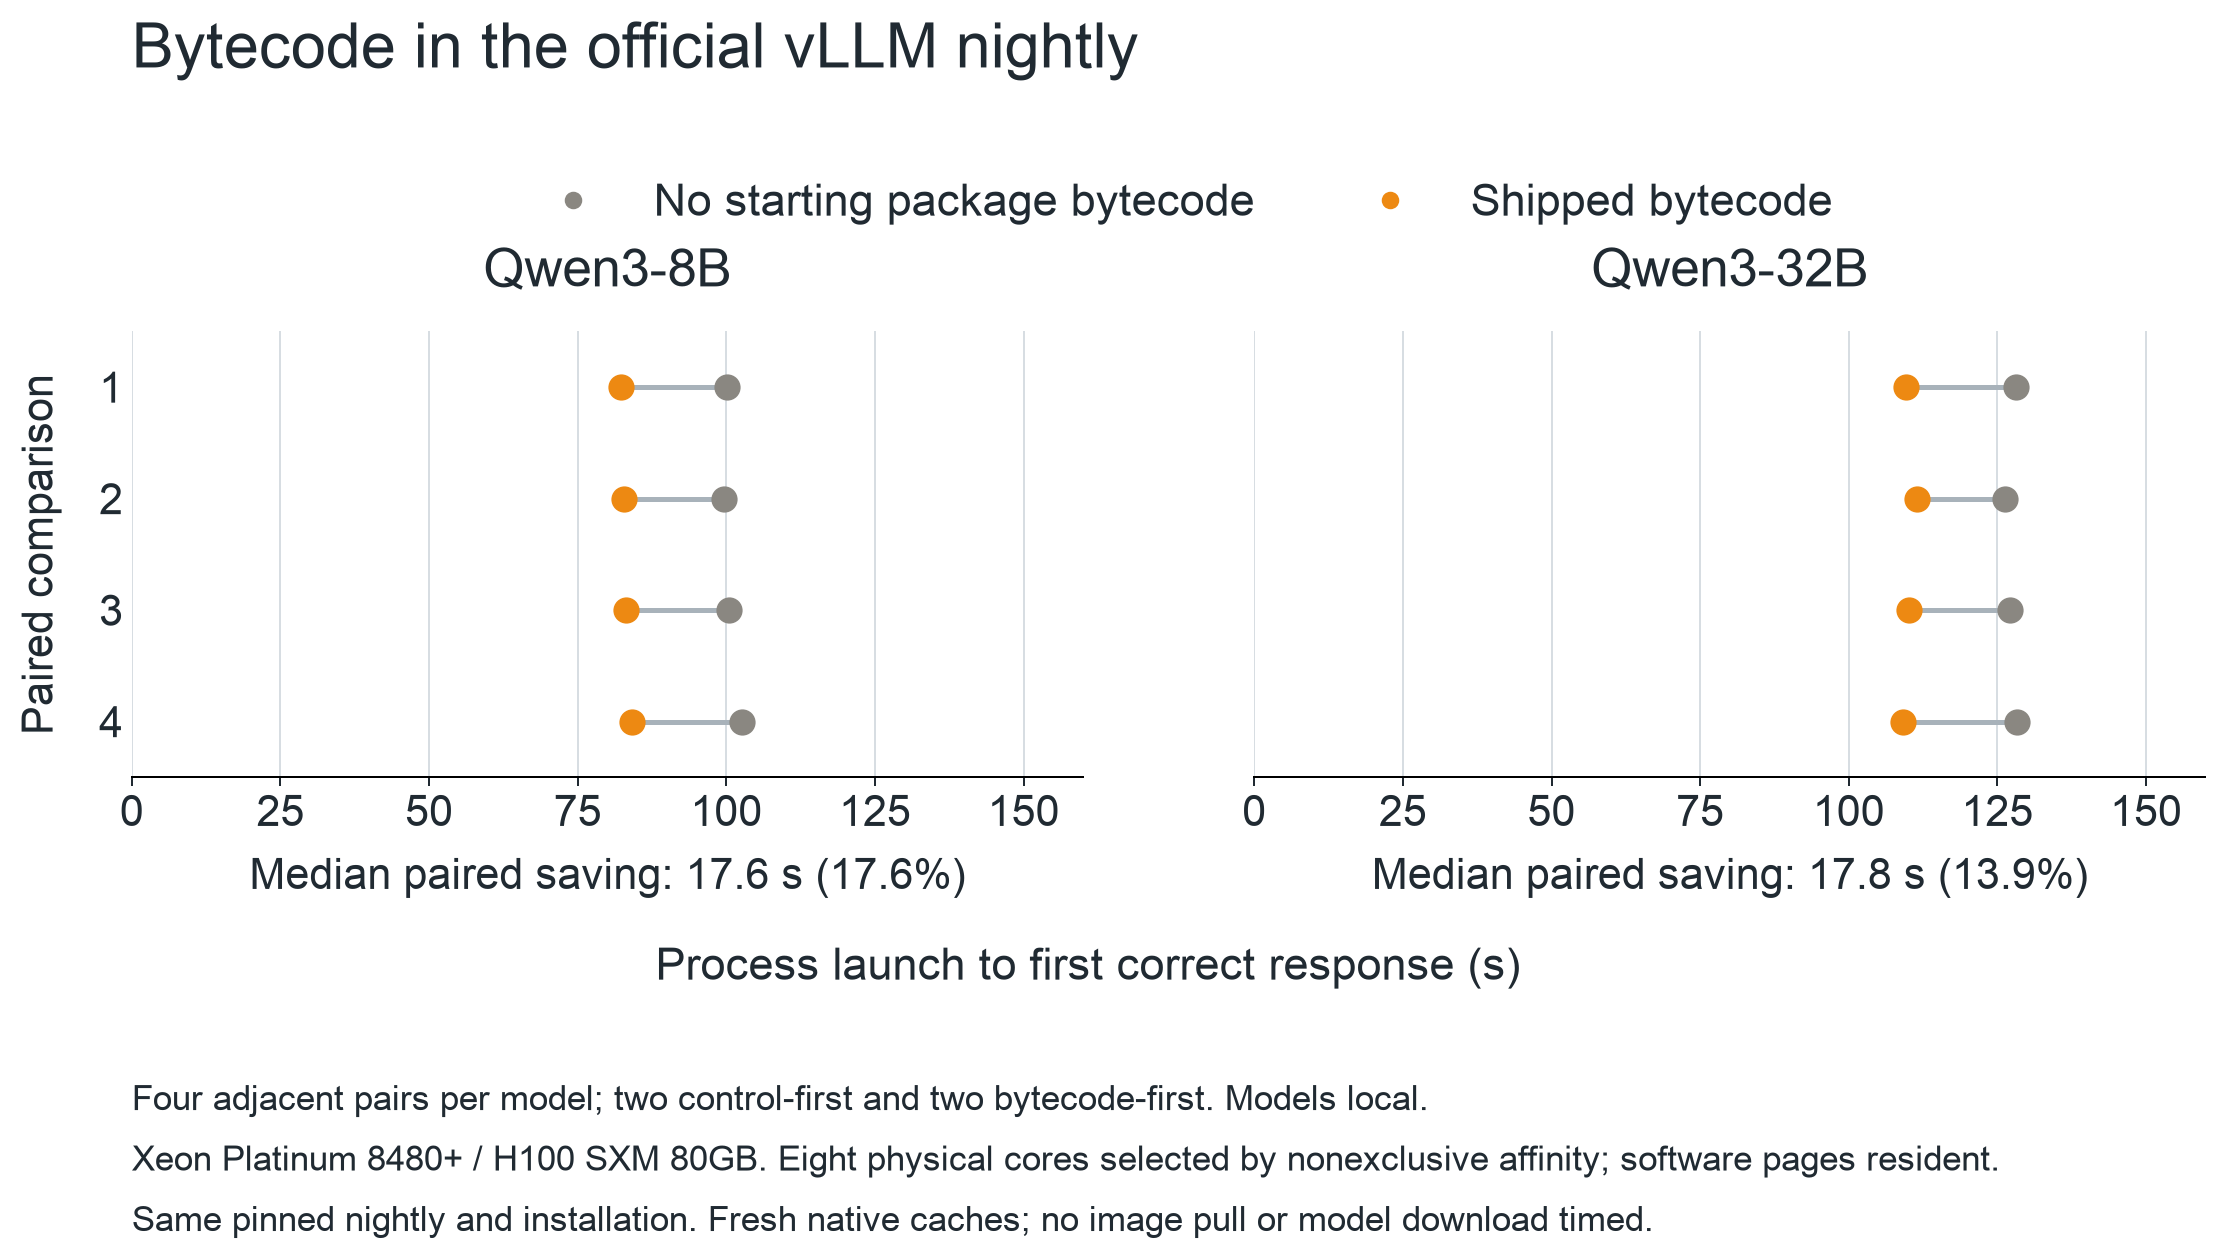
Shipping Python bytecode saved about 18 seconds per startup in H100 server benchmarks, with images and models already local.
2 posts
Shipping Python bytecode saved about 18 seconds per startup in H100 server benchmarks, with images and models already local.
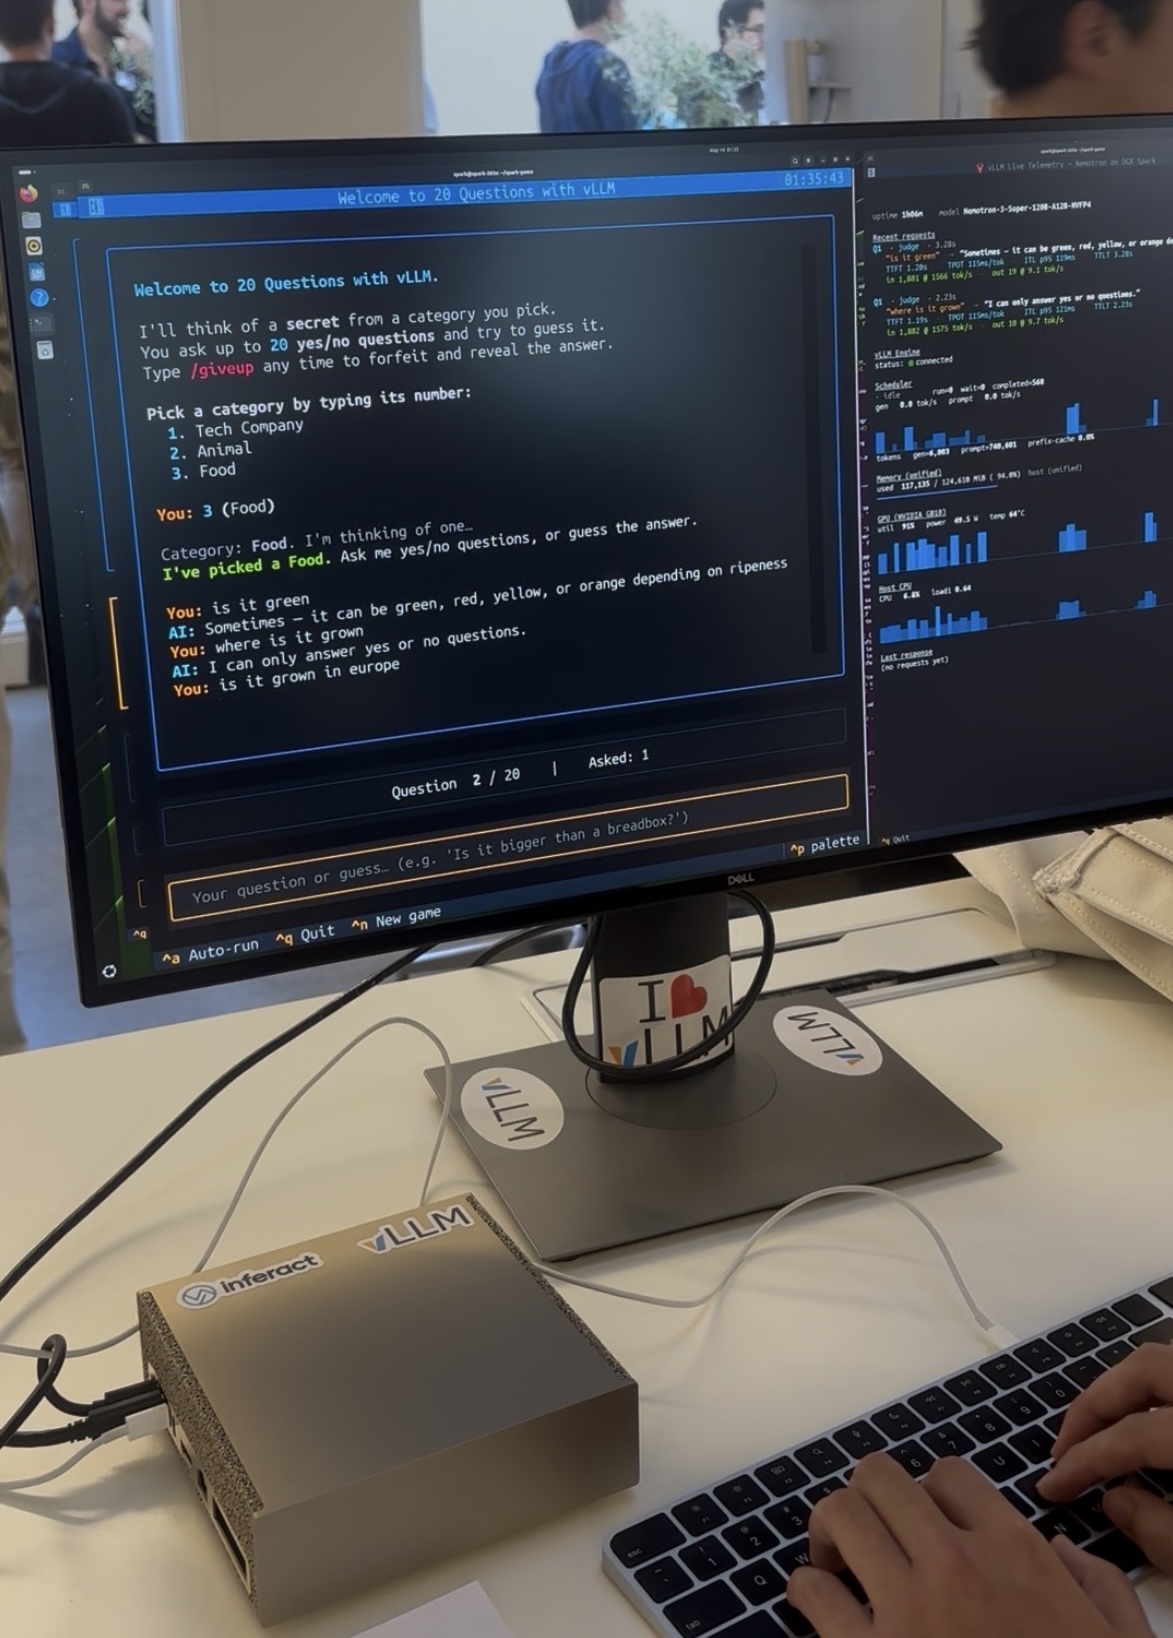
How to run vLLM on NVIDIA DGX Spark and GB10 systems, including unified memory behavior, NVFP4 Nemotron-3-Super serving, Docker deployment, Prometheus metrics, and local evaluation results.