
Day 0 support for Muse Spark Open on vLLM
·9 min read
Day-0 vLLM support for Muse Spark Open: 816B MoE, 1M context, multimodal inputs, DSpark speculative decoding, NVIDIA and AMD serving, initial TPU support, and LoRA RL.

8 posts
Day-0 vLLM support for Muse Spark Open: 816B MoE, 1M context, multimodal inputs, DSpark speculative decoding, NVIDIA and AMD serving, initial TPU support, and LoRA RL.
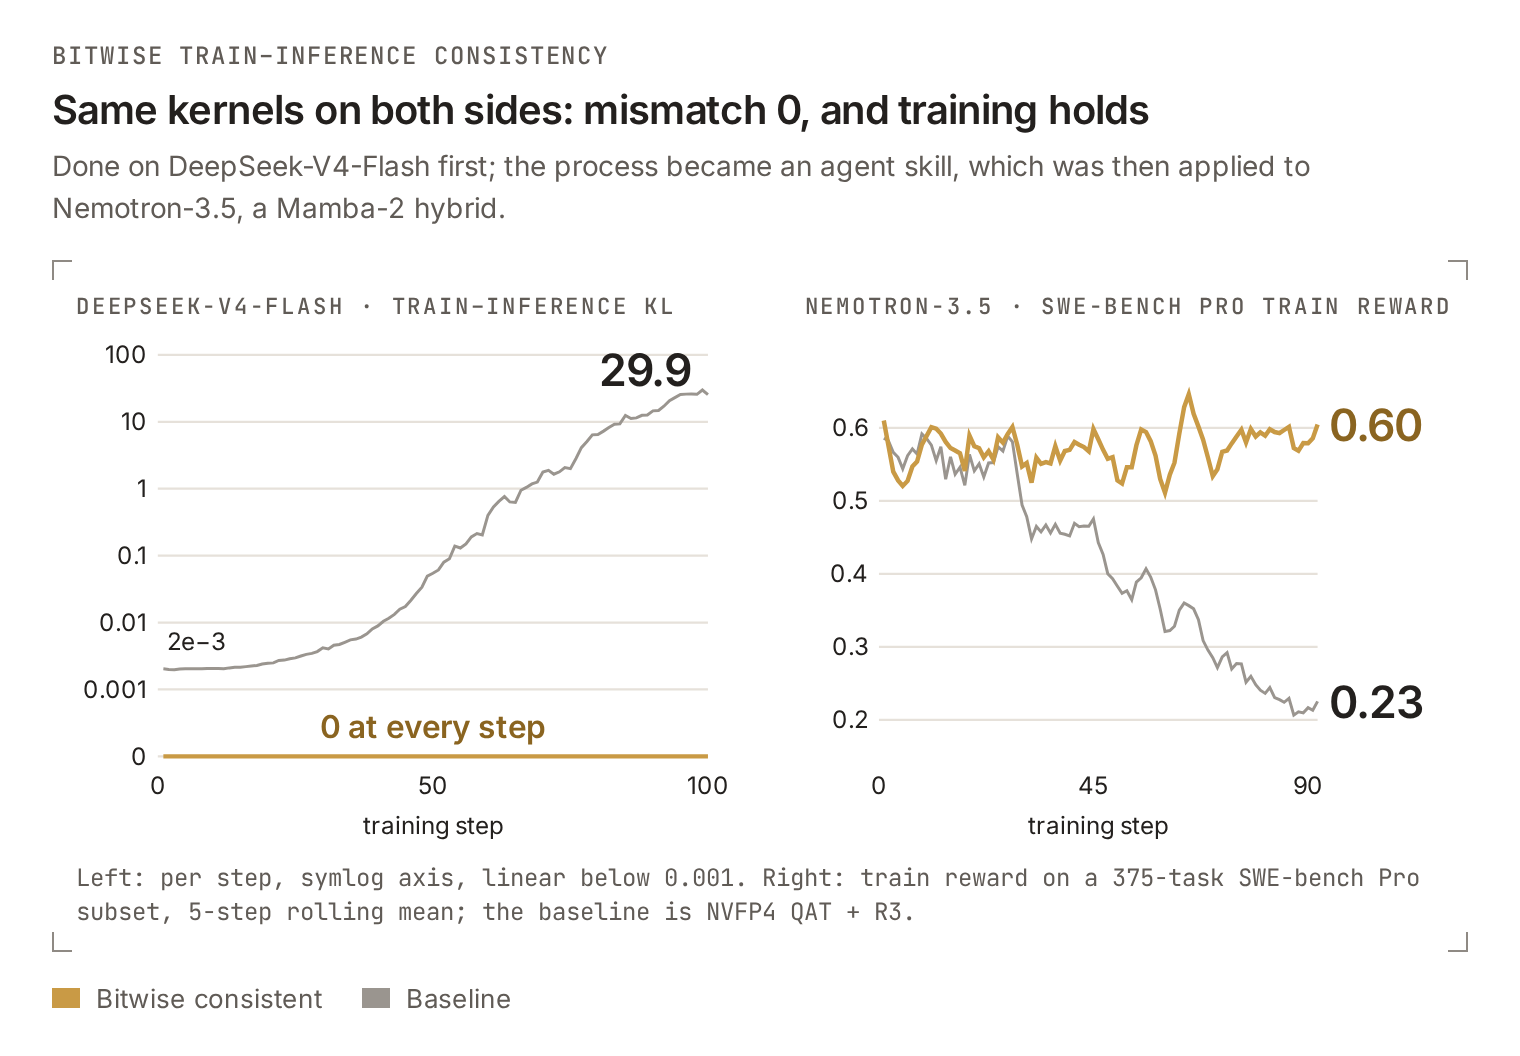
We make vLLM rollout and the training forward give bitwise identical logprobs on DeepSeek-V4-Flash and Nemotron-3.5-Lightning-30B-A3B (NVFP4), keep 91% of rollout throughput on DeepSeek-V4-Flash, and open-source the agent skill.
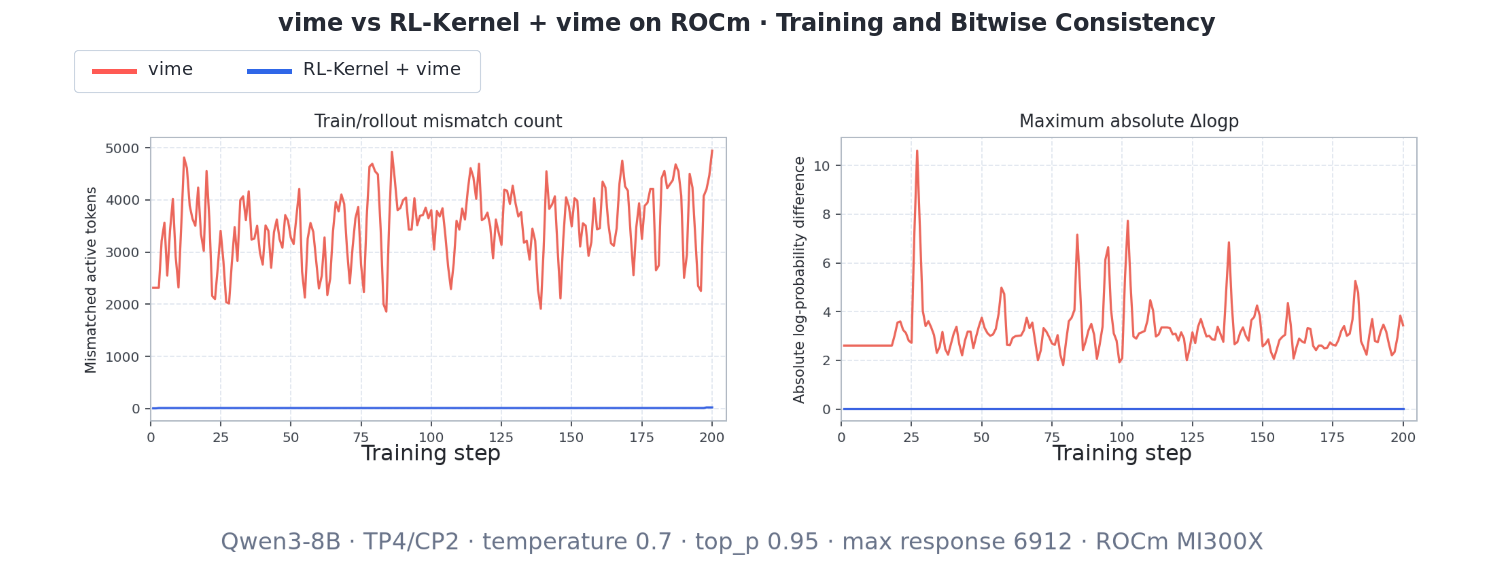
vime and RL-Kernel align selected-token logprobs bit for bit across Megatron training and vLLM rollout on AMD Instinct MI300X, with zero mismatches across 200 GRPO steps.
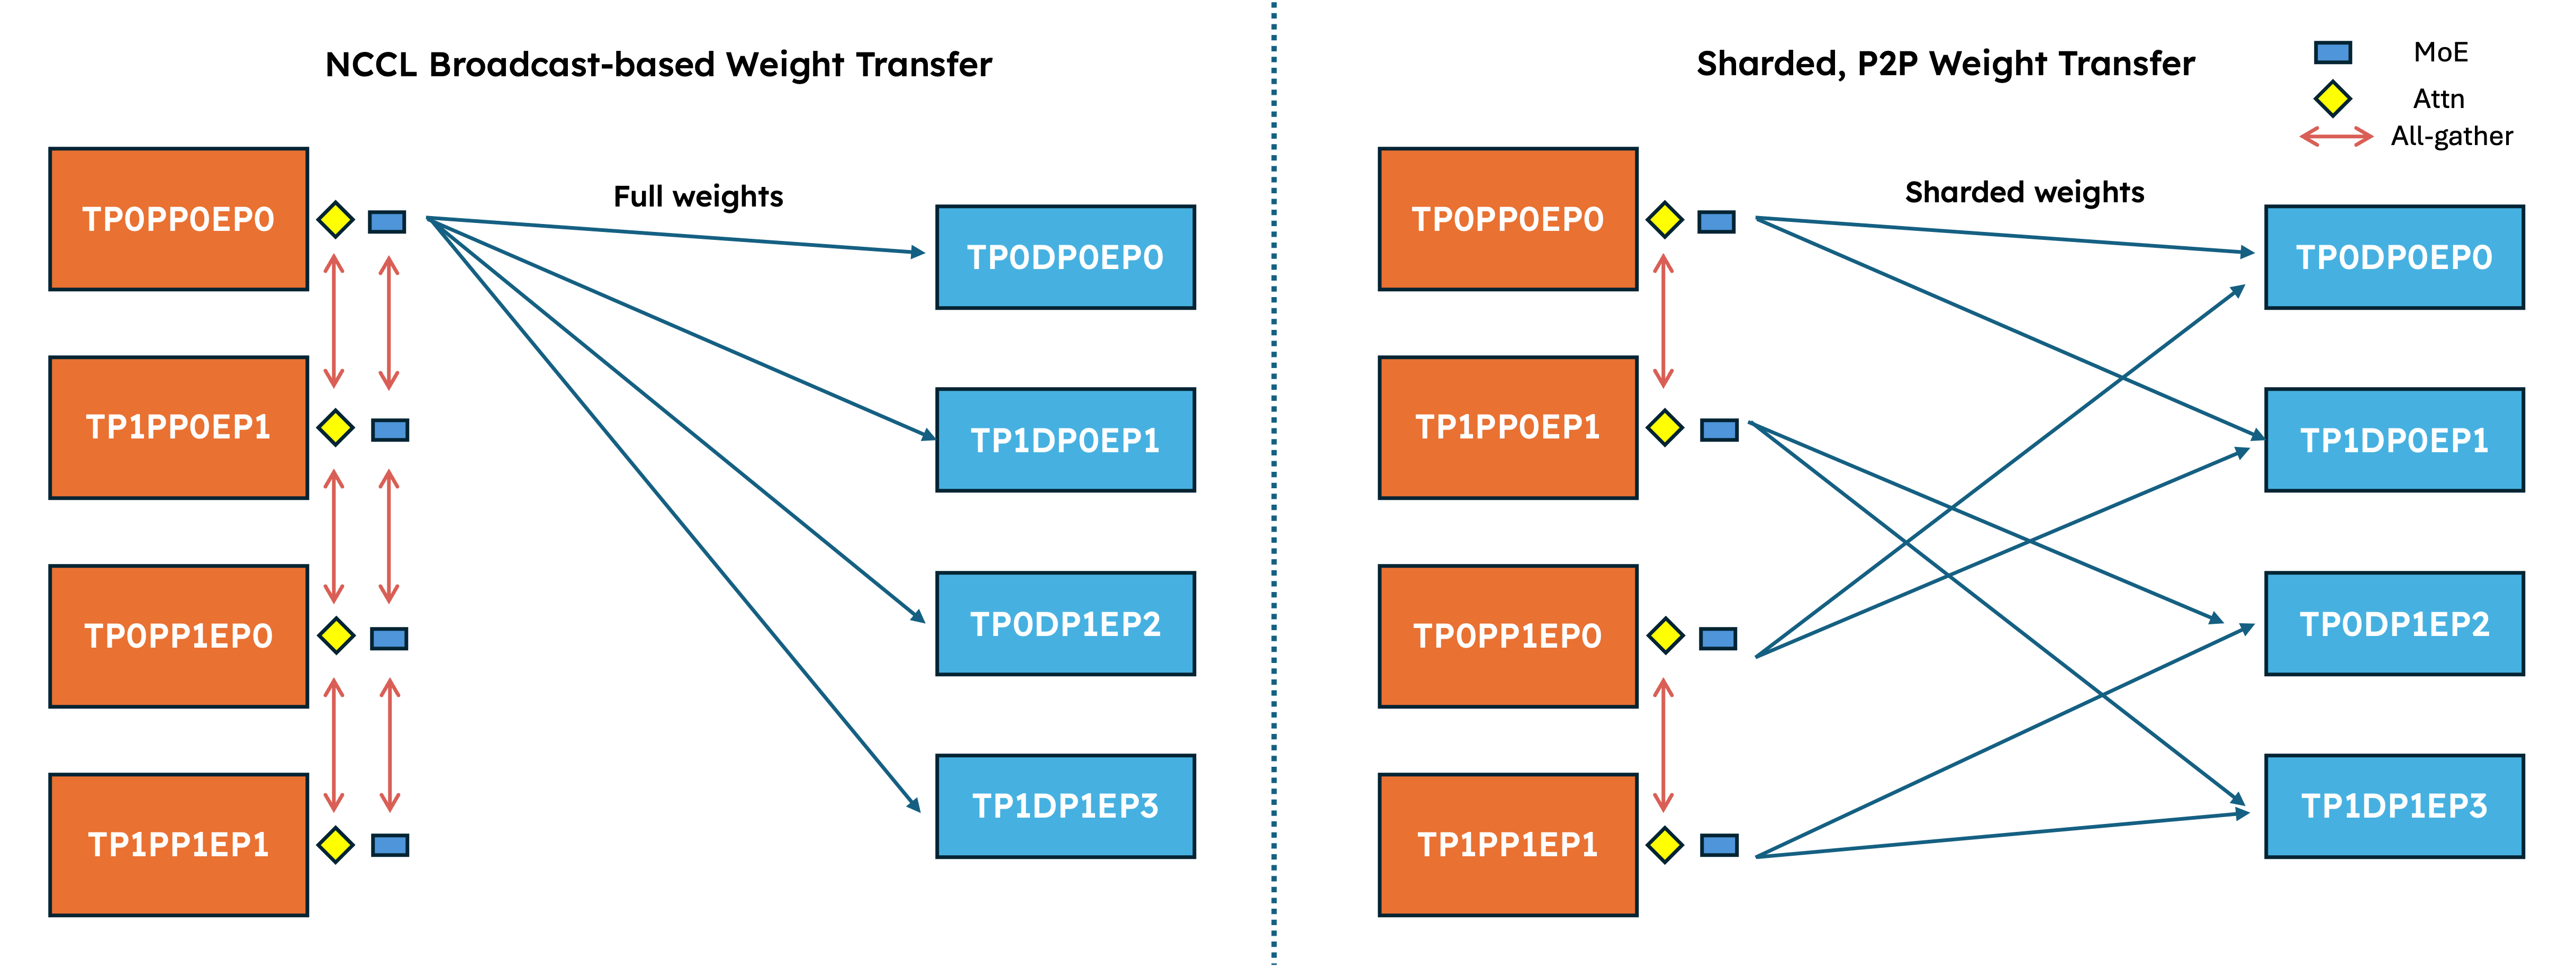
We implement a native sharded weight transfer engine in vLLM utilizing Ray Direct Transport (RDT), achieving weight transfer for the Kimi K2 model in BF16 on 48 8xH100 nodes in 7.53s
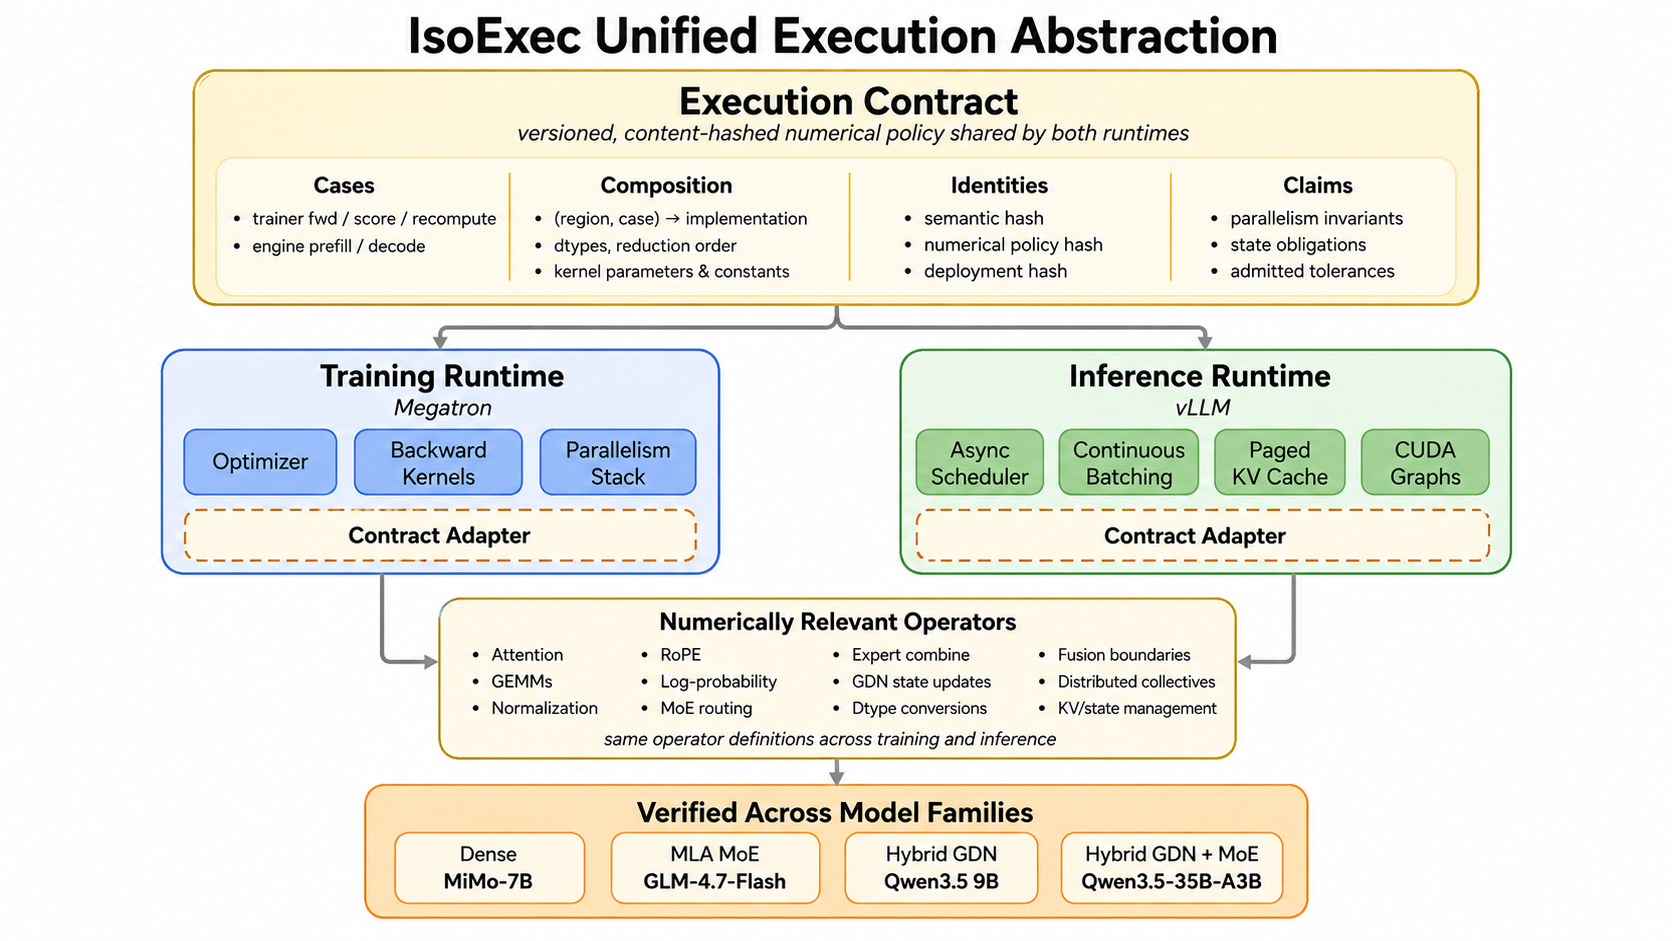
IsoExec unifies numerical execution across SkyRL's vLLM and Megatron runtimes, reducing the average rollout-versus-training logprob difference below 1e-6 on Qwen3.5-35B-A3B with 25% overhead.
Announcing ROCm support for vime, now running end-to-end on AMD Instinct MI355X GPUs with prebuilt container.
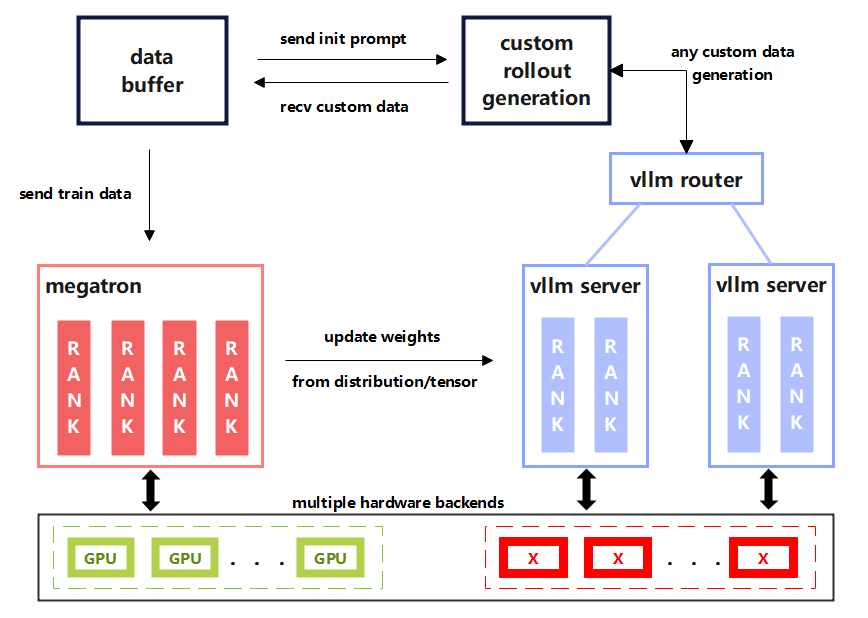
vime connects slime's training stack with vLLM rollouts to provide a simple, stable, and efficient RL post-training pipeline.

How vLLM native RL APIs standardize weight syncing and asynchronous RL serving with NCCL and CUDA IPC transfer backends, pause mode, and fixes for fragile DPEP and disaggregated rollout deployments.