
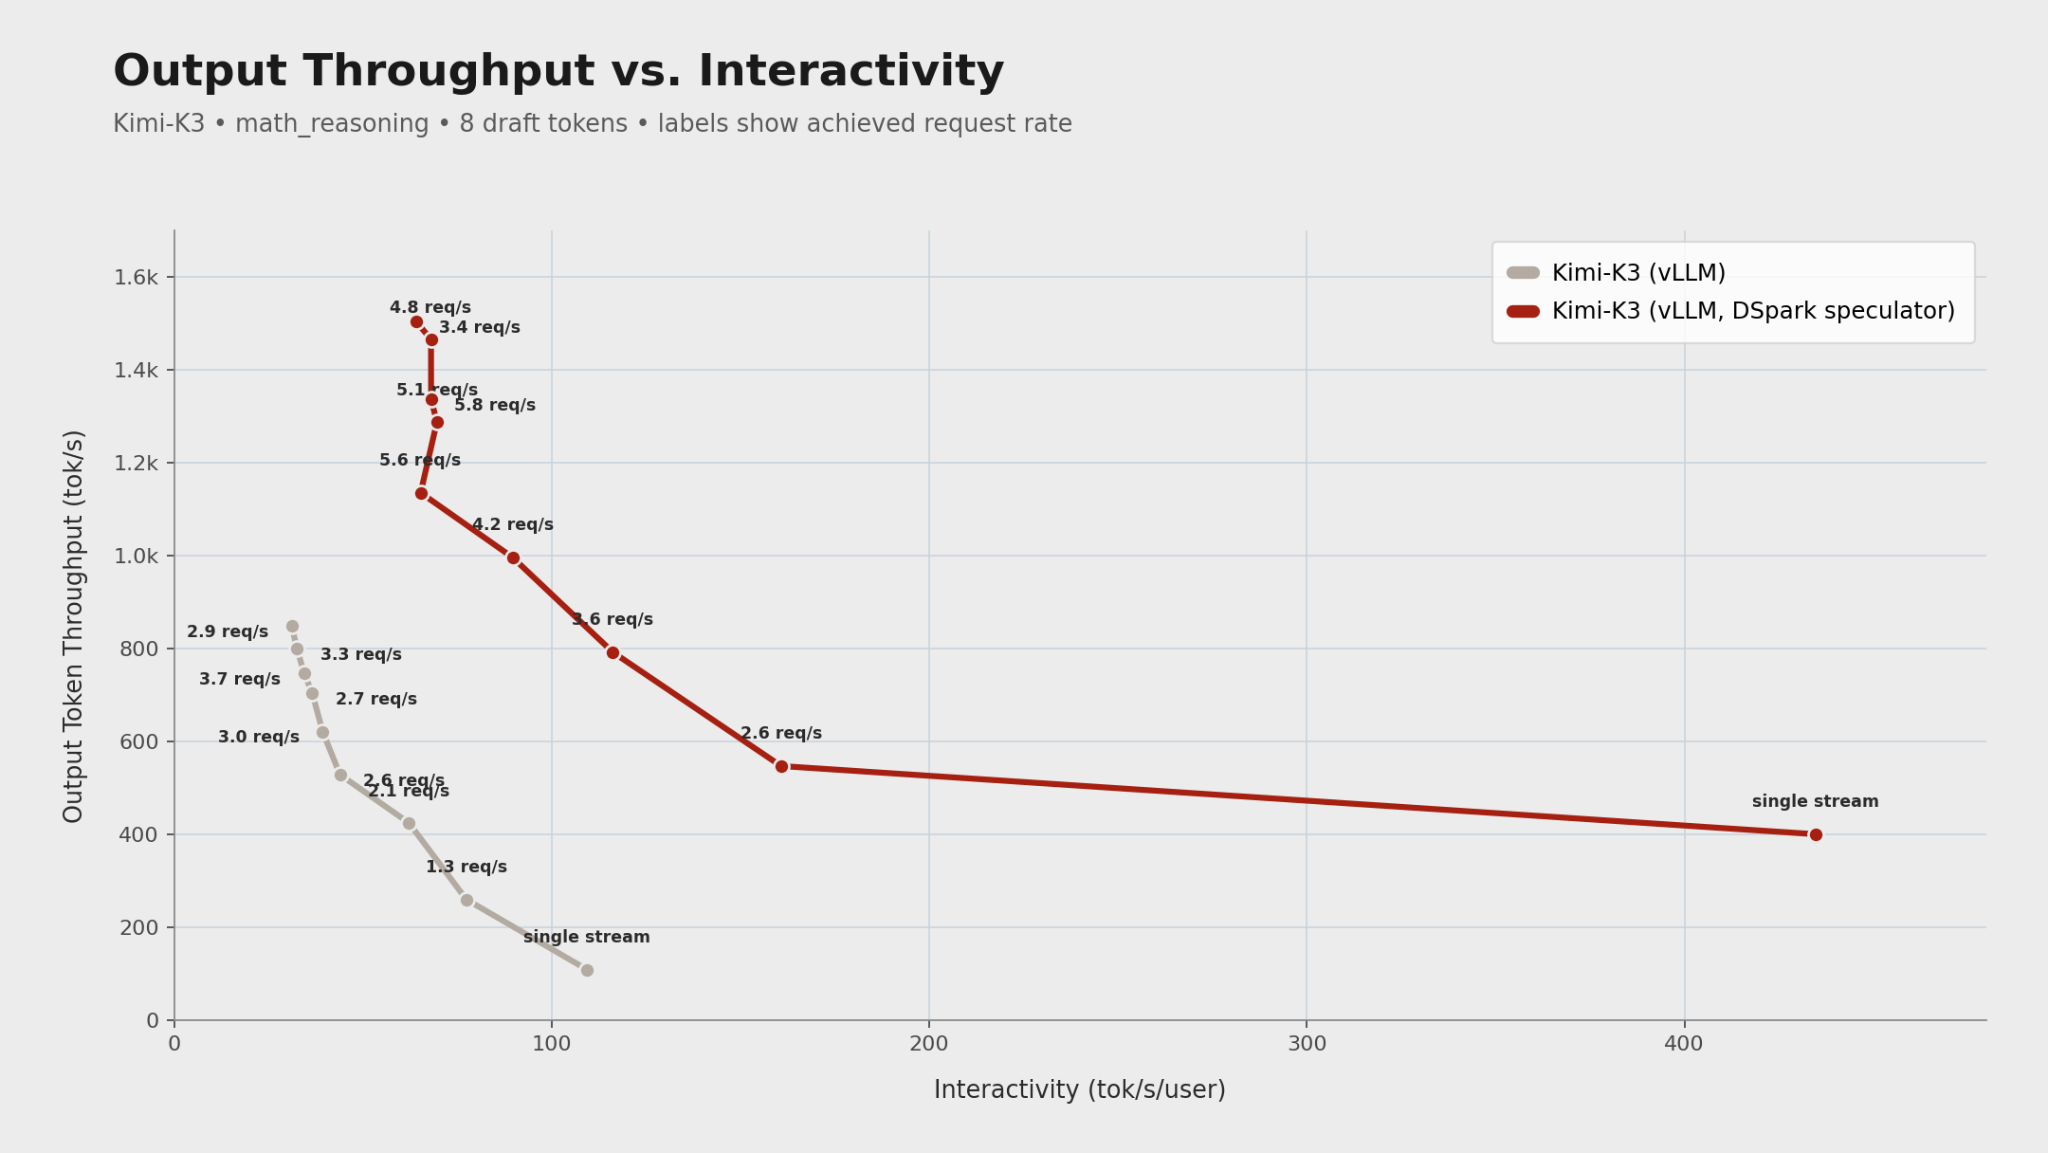
How we trained the fastest DSpark for Kimi-K3 using GB300 NVL72
·9 min read
How Speculators and Mooncake enabled multi-node DSpark training for Kimi K3.

3 posts
How Speculators and Mooncake enabled multi-node DSpark training for Kimi K3.
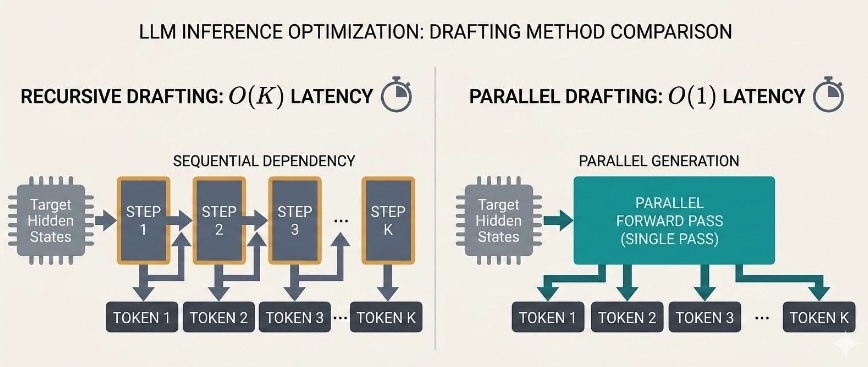
Speculators and vLLM now support P-EAGLE, DFlash, and DSpark — three parallel drafting algorithms that move beyond sequential token generation to deliver faster, simpler, and more scalable speculative decoding for LLM serving.
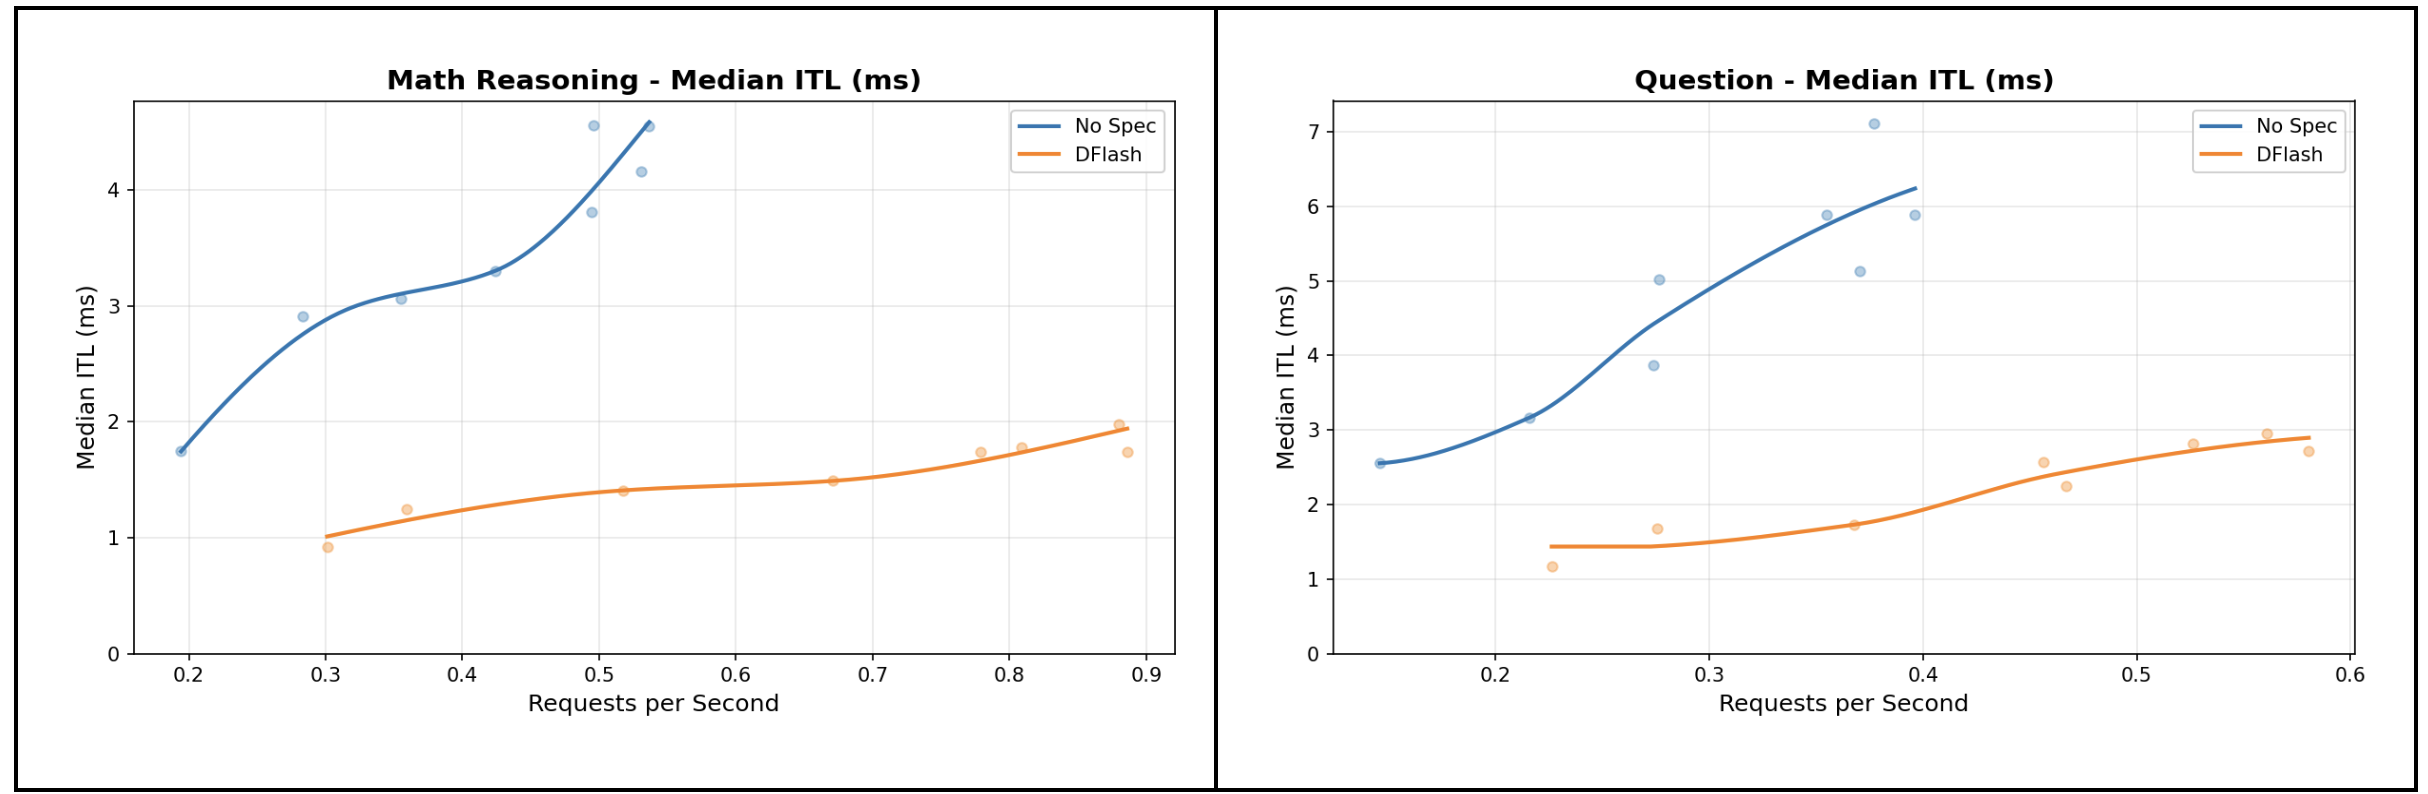
How Laguna XS.2 is served and optimized in vLLM using first-class model integration, a DFlash speculator trained with Speculators, and FP8, NVFP4, INT4, and INT8 checkpoints from LLM Compressor.